








All About Searching Algorithms: Types, Examples & Complexity
Learn all about searching algorithms, including Linear Search, Binary Search, Jump Search, Interpolation Search, Exponential Search, time complexity, and practical examples.
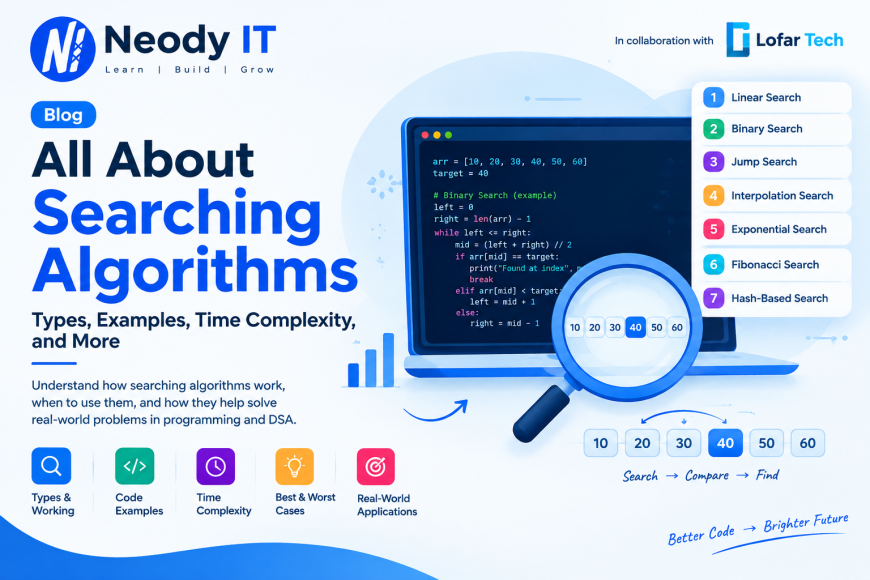
All About Searching Algorithms: Types, Examples, Time Complexity, and More
Imagine you have 100 student records, and you need to find the details of one particular student. Will you check every record one by one? Or can you find the required information more efficiently?
This is exactly the kind of problem that searching algorithms help us solve. Whenever a program needs to find a particular element in a collection of data, it uses some form of searching.
Searching is one of the fundamental concepts in Data Structures and Algorithms (DSA). You will encounter it while working with arrays, databases, file systems, search engines, and many other applications. Understanding how different searching algorithms work will also help you solve coding interview problems more efficiently.
In this guide by Neody IT in collaboration with Lofar Tech, we will explain searching algorithms step by step, including their types, working principles, best and worst cases, time complexities, practical applications, and the situations in which each algorithm is useful.
The goal is not just to memorize algorithm names. You should understand why an algorithm works, what conditions it requires, and when it makes sense to use it.
1. What Is a Searching Algorithm?
A searching algorithm is a method used to find a particular element, value, or record in a collection of data. Depending on the problem, the algorithm may return the position of an element, confirm whether it exists, or retrieve the matching information.
For example, consider the following array:
numbers = [10, 25, 30, 45, 60]Suppose you want to find the number 30. A searching algorithm examines the data according to its rules and determines that 30 is present at index 2.
Target: 30
Result: Found at index 2
Now imagine the array contains one million elements instead of five. Checking every element may require considerable work. A more suitable algorithm can reduce the number of comparisons, provided the data structure and input satisfy the algorithm's requirements.
This is why choosing the correct searching algorithm matters. Different algorithms have different requirements and performance characteristics.
2. Why Are Searching Algorithms Important?
Modern applications work with large amounts of data. A student management system searches for student records, an e-commerce website retrieves products, and a file manager helps you locate files. Searching is a fundamental operation behind many of these tasks.
Searching algorithms are important for several reasons:
- Finding data efficiently: They help locate required information within a collection.
- Reducing unnecessary comparisons: Suitable algorithms can avoid examining every element.
- Improving application performance: Efficient searching can make data retrieval faster.
- Solving DSA problems: Searching techniques appear in array, matrix, string, and optimization problems.
- Building advanced systems: Search techniques are used in databases, indexing structures, and information retrieval.
However, the fastest algorithm is not always the best choice. You must also consider whether the data is sorted, how often it changes, how much memory is available, and how frequently searches are performed.
3. Types of Searching Algorithms
There are several searching algorithms, each designed for particular situations. Some work with unsorted data, while others require sorted data or additional information about the values being searched.
The major searching techniques include:
- Linear Search
- Binary Search
- Jump Search
- Interpolation Search
- Exponential Search
- Fibonacci Search
- Hash-Based Searching
Linear and binary search are the most important starting points for beginners. Once you understand these two, the working principles of several other searching algorithms become easier to understand.
4. Linear Search: The Simplest Searching Algorithm
Linear Search, also known as sequential search, checks elements one by one until it finds the target or reaches the end of the collection.
Think about searching for a particular name in an unsorted list. If the names are not arranged alphabetically and you have no other information about their positions, checking them one by one is a straightforward approach.
4.1 How Does Linear Search Work?
Consider this array:
numbers = [12, 7, 25, 18, 40]Suppose the target value is 18. Linear search proceeds as follows:
- Check the first element, 12. It is not the target.
- Check the second element, 7. It is not the target.
- Check the third element, 25. It is not the target.
- Check the fourth element, 18. The target is found.
The algorithm returns index 3 because array indexing starts at zero in Python.
4.2 Python Implementation of Linear Search
def linear_search(arr, target):
    for index in range(len(arr)):
        if arr[index] == target:
            return index

    return -1


numbers = [12, 7, 25, 18, 40]

result = linear_search(numbers, 18)

if result != -1:
    print("Element found at index:", result)
else:
    print("Element not found")
Output:
Element found at index: 3The function returns the index of the first matching element. If the target does not exist, it returns -1.
4.3 Best, Average, and Worst Cases of Linear Search
To understand an algorithm's performance, we commonly analyze its best, average, and worst cases.
- Best case: O(1) — The target is the first element, so only one comparison is required.
- Average case: O(n) — For a typical successful search with the target equally likely to occur at any position, the algorithm examines about half the elements on average. The number of comparisons still grows linearly with n.
- Worst case: O(n) — The target is the last element or is not present, requiring up to n comparisons.
Here, n represents the number of elements in the collection.
4.4 Advantages of Linear Search
- It is simple to understand and implement.
- It works with sorted and unsorted collections.
- It does not require additional memory for the search itself.
- It works well for small datasets.
4.5 Disadvantages of Linear Search
- It may examine every element in a large collection.
- Its worst-case running time grows linearly with the input size.
- Repeated searches can become expensive when the dataset is large.
4.6 When Should You Use Linear Search?
Linear search is a good choice when the collection is small, the data is unsorted, or you need a simple search without preprocessing. It is also useful when the data structure does not support efficient random access to its elements.
5. Binary Search: Searching by Eliminating Half the Data
Binary Search is an efficient searching algorithm that repeatedly divides the search interval into two halves. Instead of checking every element, it examines the middle element and determines which half could contain the target.
But there is an important condition: binary search requires data to be sorted, or otherwise organized in a way that supports the same elimination logic.
Suppose you are searching for a word in a dictionary. You do not start from the first word and check every entry. You open a section near the middle, compare the word you want with the words there, and eliminate the half that cannot contain your answer.
Binary search follows a similar idea.
5.1 How Does Binary Search Work?
Consider the sorted array:
numbers = [10, 20, 30, 40, 50, 60, 70]Suppose you want to find 60.
- The search starts with the full array. The middle element is 40.
- Since 60 is greater than 40, the left half can be eliminated.
- The remaining search interval is [50, 60, 70].
- The middle element of this interval is 60.
- The target is found at index 5 in the original array.
The algorithm finds the target without checking every element. Each comparison reduces the remaining search interval substantially.
5.2 Python Implementation of Binary Search
def binary_search(arr, target):
    left = 0
    right = len(arr) - 1

    while left <= right:
        mid = left + (right - left) // 2

        if arr[mid] == target:
            return mid

        elif arr[mid] < target:
            left = mid + 1

        else:
            right = mid - 1

    return -1


numbers = [10, 20, 30, 40, 50, 60, 70]

result = binary_search(numbers, 60)

if result != -1:
    print("Element found at index:", result)
else:
    print("Element not found")
Output:
Element found at index: 5The expression left + (right - left) // 2 calculates the middle index. This form avoids potential integer overflow in languages with fixed-width integers when the bounds are large.
5.3 Understanding the Binary Search Conditions
The algorithm uses three important conditions:
- If the middle element equals the target, return its index.
- If the middle element is smaller than the target, continue searching in the right half.
- If the middle element is greater than the target, continue searching in the left half.
The process continues until the target is found or the search interval becomes empty.
5.4 Best, Average, and Worst Cases of Binary Search
- Best case: O(1) — The target is the middle element during the first comparison.
- Average case: O(log n) — The search interval is repeatedly reduced by approximately half.
- Worst case: O(log n) — The algorithm continues eliminating halves until the target is found or the interval becomes empty.
Binary search requires O(1) auxiliary space in the iterative implementation shown above. A recursive implementation generally uses O(log n) auxiliary stack space because the recursion depth grows logarithmically.
5.5 Advantages of Binary Search
- It is significantly more efficient than linear search on large, sorted arrays.
- It requires only logarithmically many comparisons in the worst case.
- Its iterative implementation uses constant auxiliary space.
- It is useful in many DSA problems involving sorted data and boundaries.
5.6 Disadvantages of Binary Search
- The collection must be sorted or support a suitable ordered search.
- Sorting an unsorted collection can add preprocessing cost.
- It is not efficient on every data structure. For example, repeatedly accessing middle elements in a linked list is not constant time.
5.7 When Should You Use Binary Search?
Binary search is especially useful when searching large, sorted arrays or when a problem involves finding boundaries, such as the first element greater than or equal to a target.
It is also frequently used in problems known as binary search on answer, where you search for the smallest or largest feasible value in a monotonic search space.
6. Linear Search vs. Binary Search
Both algorithms help locate elements, but their working principles and requirements are different.
| Feature | Linear Search | Binary Search |
|---|---|---|
| Approach | Checks elements one by one | Repeatedly halves the search interval |
| Requires sorted data | No | Yes, for the standard algorithm |
| Best-case time | O(1) | O(1) |
| Average-case time | O(n) | O(log n) |
| Worst-case time | O(n) | O(log n) |
| Auxiliary space | O(1) for the iterative version | O(1) for the iterative version |
| Best use case | Small or unsorted collections | Large, sorted arrays |
The practical difference becomes more noticeable as the dataset grows. Linear search may need to examine hundreds of thousands of elements, while binary search can narrow a large sorted array to a small search interval in relatively few comparisons.
However, if your data is unsorted and you only need to search once, sorting it first just to perform binary search may cost more than a simple linear search.
7. Jump Search: Searching in Fixed-Size Jumps
Jump Search is a searching algorithm designed for sorted arrays. Instead of checking every element or repeatedly halving the interval, it moves forward in jumps of a fixed size. Once it passes the target, it performs a linear search within the previous block.
7.1 How Does Jump Search Work?
Consider a sorted array containing 100 elements. Instead of examining every element, Jump Search may jump ahead by blocks of approximately 10 elements.
If the target falls between the values at two consecutive jump positions, the algorithm searches that block sequentially.
For an array of length n, the commonly used jump size is approximately the square root of n. This balances the number of jumps with the number of comparisons needed during the final linear search.
7.2 Python Implementation of Jump Search
from math import isqrt


def jump_search(arr, target):
    n = len(arr)

    if n == 0:
        return -1

    step = isqrt(n)
    start = 0
    end = step

    while start < n and arr[min(end, n) - 1] < target:
        start = end
        end += step

        if start >= n:
            return -1

    for index in range(start, min(end, n)):
        if arr[index] == target:
            return index

        if arr[index] > target:
            return -1

    return -1


numbers = [10, 20, 30, 40, 50, 60, 70, 80, 90]
print(jump_search(numbers, 70))
Output:
67.3 Time Complexity of Jump Search
- Best case: O(1), when the target is found immediately.
- Average case: O(√n) under common assumptions about target positions.
- Worst case: O(√n).
Jump Search is not generally faster than binary search on ordinary sorted arrays with efficient random access. However, it provides a useful example of how block-based searching works.
7.4 When Should You Use Jump Search?
Jump Search can be useful in certain settings where moving through blocks is convenient. For typical in-memory arrays, binary search is usually the more efficient general-purpose option.
8. Interpolation Search: Estimating Where the Target Is
Interpolation Search is another searching algorithm for sorted data. Unlike binary search, which always examines the middle position, Interpolation Search estimates the likely position of the target based on the values at the ends of the current interval.
Think about searching for a number in a sorted array ranging from 10 to 10,000. If the values are distributed approximately uniformly and your target is close to 9,000, checking the exact middle may not be the most promising first step.
Interpolation Search uses the target's value to estimate a position within the search interval.
8.1 How Does Interpolation Search Work?
The algorithm estimates the position using a formula similar to:
position = low + (
    (target - arr[low]) * (high - low)
    // (arr[high] - arr[low])
)
Here, low and high are the boundaries of the current search interval. The formula estimates where the target might appear based on the relative values at those boundaries.
Before calculating the position, the implementation must verify that the target lies between the boundary values and that the denominator is not zero.
8.2 Python Implementation of Interpolation Search
def interpolation_search(arr, target):
    low = 0
    high = len(arr) - 1

    while (
        low <= high
        and arr
        and arr[low] <= target <= arr[high]
    ):
        if arr[low] == arr[high]:
            if arr[low] == target:
                return low
            return -1

        pos = low + (
            (target - arr[low]) * (high - low)
            // (arr[high] - arr[low])
        )

        if arr[pos] == target:
            return pos

        if arr[pos] < target:
            low = pos + 1
        else:
            high = pos - 1

    return -1


numbers = [10, 20, 30, 40, 50, 60, 70, 80, 90]

print(interpolation_search(numbers, 70))
Output:
68.3 Time Complexity of Interpolation Search
- Best case: O(1), when the target is found at the first estimated position.
- Average case: O(log log n) for suitably distributed, approximately uniform data under standard assumptions.
- Worst case: O(n), when the position estimates repeatedly make poor progress.
The average-case advantage depends heavily on the distribution of values. If the data is irregularly distributed, Interpolation Search may perform worse than binary search.
8.4 When Should You Use Interpolation Search?
Interpolation Search is worth considering when the data is sorted, values are numerical, and their distribution is reasonably uniform. Binary search is generally the safer choice when the distribution is unknown or irregular.
9. Exponential Search: Finding a Range Quickly
Exponential Search is a searching algorithm used with sorted data. It first expands a search boundary exponentially, typically by doubling an index, until it finds a range that may contain the target. It then applies binary search within that range.
Instead of checking every position, the algorithm examines positions such as 1, 2, 4, 8, 16, and so on. This quickly identifies a suitable interval, particularly when the target is near the beginning of a large sorted collection.
9.1 How Does Exponential Search Work?
- Check whether the first element is the target.
- Start with an index of 1.
- Double the index while the indexed value is smaller than the target.
- Use binary search within the resulting interval.
9.2 Python Implementation of Exponential Search
def binary_search_range(arr, target, left, right):
    while left <= right:
        mid = left + (right - left) // 2

        if arr[mid] == target:
            return mid

        if arr[mid] < target:
            left = mid + 1
        else:
            right = mid - 1

    return -1


def exponential_search(arr, target):
    n = len(arr)

    if n == 0:
        return -1

    if arr[0] == target:
        return 0

    bound = 1

    while bound < n and arr[bound] < target:
        bound *= 2

    return binary_search_range(
        arr,
        target,
        bound // 2,
        min(bound, n - 1)
    )


numbers = [10, 20, 30, 40, 50, 60, 70, 80, 90]

print(exponential_search(numbers, 70))
Output:
69.3 Time Complexity of Exponential Search
- Best case: O(1).
- Worst case: O(log n).
- Auxiliary space: O(1) for the iterative implementation.
Exponential Search is particularly useful when the target is expected to be near the beginning of a sorted array. It can also be useful for searching in conceptually unbounded or very large ordered sequences, provided the data-access mechanism supports the required indexed probes.
10. Fibonacci Search: Searching with Fibonacci Numbers
Fibonacci Search is a searching algorithm for sorted arrays that uses Fibonacci numbers to divide the search interval into smaller sections.
The Fibonacci sequence starts with numbers such as 0, 1, 1, 2, 3, 5, 8, and 13. Each number after the first two is the sum of the previous two numbers.
Fibonacci Search uses these values to choose probe positions rather than dividing the interval exactly in half as binary search does.
10.1 How Does Fibonacci Search Work?
The algorithm first finds a Fibonacci number large enough to cover the array length. It then uses Fibonacci offsets to inspect positions and narrow the search interval until the target is found or no valid candidates remain.
Fibonacci Search has O(log n) worst-case time complexity on a sorted array. Its iterative implementations can use O(1) auxiliary space.
10.2 When Should You Use Fibonacci Search?
Fibonacci Search is an alternative to binary search and is mainly useful for understanding different interval-partitioning techniques. For typical in-memory arrays, binary search is generally easier to implement and maintain.
Fibonacci Search is not automatically faster than binary search. The practical performance depends on the implementation, data access costs, and hardware.
11. Hash-Based Searching: Finding Values Using a Hash Table
So far, we have discussed algorithms that search through ordered or sequential collections. Another approach is to use a hash table, a data structure designed to provide efficient lookups using keys.
A hash table uses a hash function to map a key to a location or bucket. When you search for a key, the structure uses the hash value to identify where the corresponding entry should be stored.
Hash tables are commonly used in dictionaries, sets, caches, and applications that need frequent key-based lookups.
11.1 Example of Hash-Based Searching in Python
student_marks = {
    "Rahul": 85,
    "Priya": 92,
    "Aman": 78,
    "Neha": 90
}

student = "Priya"

if student in student_marks:
    print("Marks:", student_marks[student])
else:
    print("Student not found")
Output:
Marks: 92Python dictionaries use hashing to support key-based lookups. Their lookup operations have average-case O(1) time complexity, although performance can degrade under unfavorable collision patterns.
11.2 What Are Hash Collisions?
A hash collision occurs when different keys map to the same hash-table location or bucket. Hash-table implementations use collision-resolution techniques to handle this situation.
Because collisions are possible, hash-based lookup is not guaranteed to take O(1) time in every situation. Its typical performance depends on the hash function, the table's design, and the distribution of stored keys.
11.3 Advantages of Hash-Based Searching
- It provides fast average-case lookups by key.
- It is useful for membership checks and key-value retrieval.
- It works well when many searches must be performed on the same collection.
11.4 Limitations of Hash-Based Searching
- It generally requires additional memory for the hash table.
- It does not naturally keep keys sorted.
- Its performance depends on hashing and collision resolution.
- Creating the table from an existing collection adds preprocessing cost.
Hash-based searching is often a practical choice when you need repeated lookups by key and do not require the data to remain sorted.
12. Best Case, Average Case, and Worst Case Explained
If you want to understand searching algorithms properly, you need to understand how their performance is measured. The same algorithm can take different amounts of work depending on the input.
12.1 Best Case
The best case describes the most favorable input for an algorithm. For example, linear search has a best-case time complexity of O(1) when the target is the first element.
12.2 Average Case
The average case describes the expected amount of work under a specified distribution of inputs or target positions. Its exact meaning depends on the assumptions being made.
For example, if a successful linear search is equally likely to find the target at any position, it examines about half the elements on average. Its average-case time complexity is still O(n).
12.3 Worst Case
The worst case describes the maximum work required for an input of a given size, within the algorithm's specified operating conditions.
In linear search, the worst case occurs when the target is the last element or does not exist. The algorithm may examine every element.
Worst-case analysis is useful because it helps us understand how an algorithm behaves when the input is particularly unfavorable.
13. Time Complexity Comparison of Searching Algorithms
The following table summarizes the common time complexities of the searching techniques discussed in this article. These values assume the algorithms' normal operating conditions, such as sorted input for binary, jump, interpolation, exponential, and Fibonacci search.
| Algorithm | Best Case | Average Case | Worst Case |
|---|---|---|---|
| Linear Search | O(1) | O(n) | O(n) |
| Binary Search | O(1) | O(log n) | O(log n) |
| Jump Search | O(1) | O(√n) | O(√n) |
| Interpolation Search | O(1) | O(log log n) under suitable uniform-distribution assumptions | O(n) |
| Exponential Search | O(1) | O(log n) | O(log n) |
| Fibonacci Search | O(1) | O(log n) | O(log n) |
| Hash-Table Lookup | O(1) in favorable cases | O(1) under typical hashing assumptions | O(n) in unfavorable collision scenarios |
Here, n is the number of elements. The table describes algorithmic growth rates, not exact execution times. Actual performance also depends on implementation details, memory access, preprocessing, and the characteristics of the input.
For example, O(log n) generally grows more slowly than O(n) as n becomes large. That is why binary search is usually preferable to linear search when searching a large, sorted array.
14. How to Choose the Right Searching Algorithm
Knowing multiple algorithms is useful, but the real skill is choosing the right one for the problem.
Use Linear Search When:
- The collection is small.
- The data is unsorted.
- You need a simple solution for a single search.
- The data structure does not support efficient random access.
Use Binary Search When:
- The data is sorted.
- You need efficient searching in an array.
- You are searching for a boundary or threshold.
- You need to solve a problem using binary search on answer.
Consider Jump Search When:
- The data is sorted.
- A block-based search approach suits the problem.
- You want to study alternatives to binary search.
Consider Interpolation Search When:
- The data is sorted and numerical.
- Values are distributed approximately uniformly.
- Estimating the target position is likely to reduce comparisons.
Consider Exponential Search When:
- The data is sorted.
- The target may be near the beginning.
- You need to identify a search range before applying binary search.
Consider Hash-Based Searching When:
- You need frequent key-based lookups.
- You want to check membership efficiently.
- You do not need the collection to remain sorted.
Always evaluate the complete problem rather than selecting an algorithm based only on its time complexity. Sorting costs, memory usage, data updates, and the number of searches can all affect the final decision.
15. Common Mistakes Beginners Make While Learning Searching
Searching algorithms are not particularly difficult once their logic is clear. However, some implementation mistakes can cause incorrect results or unnecessary performance problems.
15.1 Using Binary Search on Unsorted Data
Binary search relies on the ordering of the elements. If the collection is not sorted, the algorithm cannot reliably determine which half to eliminate.
15.2 Confusing an Index with a Value
If a search returns index 4, it means the target was found at position 4 in a zero-indexed collection. It does not mean that the target value itself is 4.
15.3 Incorrect Binary Search Boundaries
Binary search commonly uses left and right pointers to represent the current search interval. Incorrectly updating these pointers can skip valid elements or cause an infinite loop.
In the implementation used earlier, the search interval is inclusive, so the loop continues while left <= right.
15.4 Forgetting Edge Cases
Always test an algorithm with an empty collection, a single element, a target at the first position, a target at the last position, and a target that does not exist.
15.5 Ignoring Duplicate Values
If an array contains multiple copies of a target, a standard binary search may return any matching position it encounters. If a problem asks for the first or last occurrence, you need to modify the search logic to find the appropriate boundary.
15.6 Ignoring Preprocessing Costs
Binary search is efficient on sorted arrays, but sorting an unsorted collection takes additional time. If you need only one search, linear search may be more practical. If you need many searches on mostly unchanged data, sorting once and then using binary search may be worthwhile.
16. Searching Algorithms in Real-World Applications
Searching algorithms are used in many areas of software development. The exact technique depends on the data structure, the type of information being searched, and the application's requirements.
- Databases: Database systems use indexes and other data structures to locate records efficiently.
- Search Engines: Information retrieval systems use indexes, ranking methods, and retrieval algorithms to find relevant documents.
- E-Commerce: Product catalogs use searching, filtering, and indexing to help customers find items.
- Operating Systems: File management tools locate files and directories using metadata and search structures.
- Student Management Systems: Applications retrieve student records, marks, attendance, and enrollment information.
- Software Development: Developers use searching to locate elements in arrays, objects, maps, and other collections.
In production systems, searching often involves more than a single textbook algorithm. Databases may use B-trees, hash indexes, or specialized indexes depending on the query. Search engines combine retrieval with ranking and relevance calculations.
Understanding fundamental searching algorithms gives you a foundation for learning these more advanced techniques.
17. Frequently Asked Questions About Searching Algorithms
What is a searching algorithm in DSA?
A searching algorithm is a method used to find a target element or record in a collection. Common examples include Linear Search and Binary Search.
Which searching algorithm is the simplest?
Linear Search is generally the simplest because it checks elements one by one until it finds the target or reaches the end of the collection.
Which searching algorithm is the fastest?
There is no single fastest algorithm for every situation. Binary Search is highly efficient for sorted arrays, while hash tables provide average-case O(1) key lookups. The best choice depends on the data structure, input, and required operations.
Why does Binary Search require sorted data?
Binary Search uses the ordering of the elements to determine which half can be eliminated. Without a suitable ordering, the comparison with the middle element cannot reliably identify the correct half.
What is the difference between Linear Search and Binary Search?
Linear Search checks elements sequentially and works with unsorted data. Binary Search repeatedly halves a sorted search interval and has O(log n) worst-case time complexity on arrays.
What is the best-case time complexity of Linear Search?
Its best-case time complexity is O(1), because the target may be the first element examined.
What is the worst-case time complexity of Binary Search?
Binary Search has O(log n) worst-case time complexity on a sorted array when each middle element can be accessed in O(1) time.
Can Binary Search work on a linked list?
Binary-search logic can be adapted to other ordered structures, but a linked list does not support efficient random access to its middle element. Repeatedly locating middle nodes can remove the usual performance advantage. Binary Search is most commonly used with arrays and other structures that support efficient indexed access.
What is the difference between searching and sorting?
Searching finds an element or record in a collection. Sorting arranges elements according to a specified order. Sorting can make some searching algorithms more efficient, but the two operations serve different purposes.
Which searching algorithms should beginners learn first?
Start with Linear Search and Binary Search. Understand their implementation, edge cases, and time complexity. Then move to Jump Search, Interpolation Search, Exponential Search, and hash-based lookups.
18. Practice These Searching Algorithm Problems
Reading an algorithm's explanation is a good starting point, but implementing it yourself is where the real learning happens. Try solving these problems in order.
- Find a target in an unsorted array using Linear Search.
- Implement Binary Search on a sorted array.
- Return -1 when the target is not present.
- Find the first occurrence of a target in a sorted array with duplicates.
- Find the last occurrence of a target in a sorted array.
- Find the insertion position of a target in a sorted array.
- Search for an element in a rotated sorted array.
- Find the first element greater than or equal to a target.
- Search for a target in a two-dimensional sorted matrix.
- Solve a binary-search-on-answer problem.
While solving these problems, do not focus only on getting the correct output. Try to explain why your approach works and analyze its time and space complexity.
If you can explain why Binary Search eliminates half of the search space at every iteration, you already understand one of the most important ideas in DSA.
Conclusion: Understand the Logic, Not Just the Algorithm Names
Searching algorithms help programs find the information they need from a collection of data. Linear Search checks elements one by one, Binary Search repeatedly halves a sorted search interval, and techniques such as Jump Search, Interpolation Search, and Exponential Search use different strategies to reduce unnecessary comparisons.
Hash-based searching takes a different approach by using a hash table to support efficient key-based lookups. Each technique has its own requirements, advantages, and limitations.
If you are learning Data Structures and Algorithms, start with Linear Search and Binary Search. Practice their implementations, understand the best, average, and worst cases, and learn when each algorithm is appropriate.
Remember, writing code that works is only one part of programming. Understanding why it works and how efficiently it runs is what helps you become a stronger problem solver.
This article is brought to you by Neody IT in collaboration with Lofar Tech, with the goal of making programming and DSA concepts easier to understand through practical explanations.
Keep learning, keep practicing, and build your DSA foundation one concept at a time.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0